Master Agentic RAG architecture in 2026. Learn query routing, corrective retrieval loops, self-grading pipelines, and production implementation code.
Agentic RAG Architecture in 2026: The Ultimate Developer Guide
Dumping thousands of unstructured documents into a vector database and running top-k cosine similarity search was once considered the gold standard for enterprise artificial intelligence. In early prototypes, naive Retrieval-Augmented Generation (RAG) delivered quick wins. Yet, as engineering teams scaled these pipelines into production, the cracks surfaced immediately: irrelevant context chunks, hallucinated answers based on partial facts, retrieval failures on multi-hop questions, and an inability to recognize when internal data sources simply lack the answer.
The solution driving modern software engineering is Agentic RAG Architecture in 2026. Rather than treating retrieval as a passive, linear conveyor belt, agentic RAG transforms information retrieval into an active, iterative reasoning loop. Autonomous agents evaluate user intent, route queries across specialized indexes, grade retrieved documents for true semantic relevance, rewrite confusing prompts, and trigger external web lookups when local knowledge runs dry.
At ISMARTANJI CREATIONS, we deliver battle-tested, practitioner-grade blueprints for modern software builders. Following our foundational guides on LangGraph vs CrewAI in 2026: Multi-Agent Orchestration & State Machine Comparison and How to Master Essential Model Context Protocol in 2026, this comprehensive guide dissects the core mechanics, architectural patterns, production trade-offs, and practical Python implementation of agentic RAG.
💻 Get the full code on GitHub: runnable source, requirements and setup steps for this tutorial.
1. Core Mechanics: Naive RAG vs. Agentic RAG
To build resilient knowledge systems, developers must recognize why linear retrieval fails where autonomous control loops succeed.
The Failure Modes of Naive RAG
Naive RAG operates under an unrealistic assumption: that top-k similarity search will always surface the precise passages needed to answer any question. When tested in real applications, three fatal bugs occur:
- Semantic Drift and Distraction: High vector similarity does not guarantee relevance. A paragraph containing identical keywords may answer a completely different question, polluting the model’s context window.
- Missing Knowledge Silence: When the database contains no matching records, naive pipelines still pass whatever distant chunks scored highest, forcing the language model to guess or fabricate facts.
- Multi-Hop Blind Spots: Complex business questions often require pulling fact A from an operations document and fact B from a financial report. Single-turn vector searches cannot chain these dependencies together.
The Four Foundational Pillars of Agentic RAG
Agentic RAG overcomes these limitations by embedding decision-making logic throughout the retrieval process:
- Pillar 1: Routing. An agent inspects incoming requests and determines whether to consult structured SQL databases, unstructured vector indexes, live web search, or skip retrieval entirely for basic greetings.
- Pillar 2: Document Grading. Every retrieved chunk passes through a lightweight classification step that checks whether the content truly answers the user question.
- Pillar 3: Query Reformulation. If retrieved passages fail grading, an optimizer agent analyzes the failure, strips out ambiguous phrasing, and queries the index with a fresh formulation.
- Pillar 4: Grounding Verification. Before delivering an answer to the end user, a verifier node checks whether the generated sentences are strictly supported by the retrieved facts, designed to reduce unsupported claims.
2. Architectural Comparison Matrix
| Feature | Naive RAG (2023–2024) | Advanced RAG (2024–2025) | Agentic RAG (Representative 2026 Architecture) |
|---|---|---|---|
| Logic Flow | Static linear script | Fixed pre/post-retrieval pipeline | Autonomous state graph with feedback loops |
| Data Access | Single hardcoded index | Hybrid fusion | Semantic/SQL/API/Web routers |
| Validation | No context validation | Re-ranking (Cohere/Cross-Encoder) | Binary and graded relevance evaluation nodes |
| Error Handling | Fails on failure | Returns low confidence score | Rewrites query or triggers external search |
| Context Grounding | Ungrounded / High Hallucination Risk | Partial Re-ranking Filter | Relevance-Graded with Active Verification |
3. Deep-Dive: The Essential Agentic RAG Design Patterns
Four commonly used design patterns are useful when building agentic retrieval systems:
Pattern 1: Router-Based RAG (Semantic Intent Dispatch)
Not every incoming user prompt requires searching gigabytes of documentation. An intelligent router acts as the front gate of your system:
- Vector Routing: Technical specifications, engineering policies, and historical customer interactions flow to high-speed vector stores such as those covered in our analysis of 7 Breakthrough AI Vector Databases for Developers in 2026.
- Tabular / Structured Routing: Inquiries regarding exact pricing tables, inventory counts, or financial metrics route to PostgreSQL or Snowflake via text-to-SQL agents.
- Direct Model Execution: Conversational queries, code formatting requests, or mathematical logic route straight to model generation without wasting retrieval compute.
Pattern 2: Corrective RAG (CRAG)
Corrective RAG introduces self-healing retrieval. When an agent queries local documentation, a dedicated evaluator grades the retrieved chunks:
- High Confidence (Correct): The chunks pass directly to the response synthesizer.
- Ambiguous Confidence (Ambiguous): The system combines the filtered chunks with a targeted web search query to fill gaps.
- Zero Confidence (Incorrect): The agent discards the internal chunks entirely, queries a web search engine or external API, and retrieves live data to construct the answer.
Pattern 3: Self-Reflective RAG (Self-RAG)
Self-RAG builds reflection checkpoints directly into generation:
- Retrieve on Demand: The model decides whether external knowledge is even necessary before executing queries.
- Critique Retrieval: The model scores each retrieved chunk for supportiveness.
- Critique Generation: Once an answer draft is produced, a verification pass inspects each sentence. If an unsupported statement appears, the generator is forced to revise the output or flag the unverified claim explicitly.
Pattern 4: Graph-Augmented Multi-Hop RAG
When business questions require traversing relationships between entities (such as microservice dependencies, corporate subsidiaries, or supply chain networks), pure vector distance fails. Combining vector search with knowledge graphs allows the agent to traverse relational nodes before fetching document chunks, can improve multi-hop retrieval by combining graph relationships with document retrieval.
4. Hands-on Reference Implementation: Building a Self-Correcting RAG Agent in Python
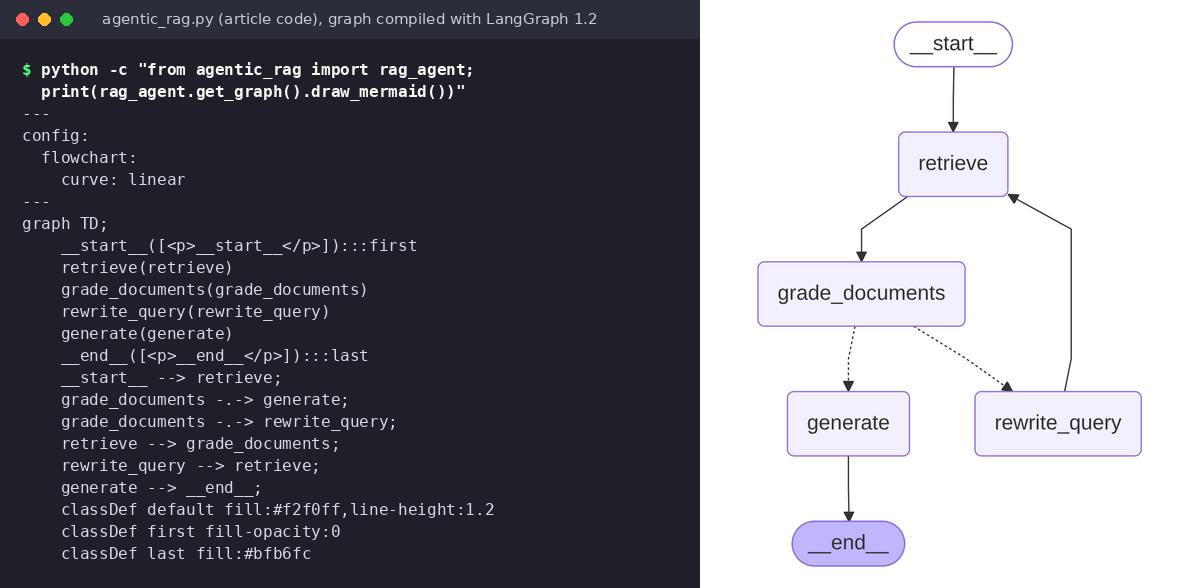
The complete reference implementation defines a StateGraph with retrieve, grade_documents, rewrite_query, and generate nodes, implementing conditional edge routing to ensure self-correction and guard against infinite loops:
Note: The example below uses a small mock knowledge base to demonstrate graph control flow. It is intentionally simplified and does not implement production vector retrieval.
5. Production Engineering: Latency, Cost, and Reliability
- Slashing Latency with Parallel Grading: Run asynchronous Python (asyncio.gather) to score retrieved passages concurrently, or deploy 1B to 3B small language models locally.
- Controlling Token Expenses with Prefix Caching: Utilize KV cache reuse for static system prompts to minimize repetitive token overhead across multi-turn agent evaluations.
- Comprehensive Pipeline Telemetry: Connect distributed tracing tools like Langfuse or Arize Phoenix to trace per-node latency and token expenditures. Review our guide to 7 Breakthrough AI Observability Platforms for Developers in 2026.
6. Recommended Reading & Developer Resources
- LangGraph vs CrewAI in 2026: Multi-Agent Orchestration & State Machine Comparison
- How to Master Essential Model Context Protocol in 2026
- 7 Breakthrough AI Vector Databases for Developers in 2026
- 7 Breakthrough AI Observability Platforms for Developers in 2026
- 7 Breakthrough AI Coding Assistants for Developers in 2026
7. Frequently Asked Questions (FAQ)
What is the fundamental difference between standard RAG and Agentic RAG?
Standard RAG follows a rigid, one-way pipeline that injects top vector matches directly into prompts. Agentic RAG wraps retrieval in an active reasoning loop that grades documents, rewrites suboptimal queries, and verifies groundedness before responding.
Does Agentic RAG increase inference latency for end users?
When optimized with parallel grading and lightweight models for routing, agentic RAG adds only bounded routing overhead while substantially improving retrieval relevance and preventing ungrounded generations.
How does Agentic RAG prevent endless query rewriting loops?
Production graphs track iteration counts to cap rewrites at 2 attempts, falling back gracefully to external web search or transparent refusal if no relevant documents exist.
Which models work best as document graders and routers in 2026?
Lightweight models like GPT-4o-mini, Claude 3.5 Haiku, or locally hosted Llama-3.2-3B excel at rapid routing and grading at minimal token costs.
8. Summary & Action Plan
Agentic RAG replaces brittle linear retrieval with self-evaluating autonomous graphs, designed to improve grounding and reduce unsupported answers in production environments.
Your 5-Step Action Checklist:
- Audit your retrieval stack for query failure modes
- Implement document relevance grading nodes
- Configure intelligent intent-based query routing
- Add self-correcting query reformulation loops
- Instrument real-time distributed telemetry with Langfuse or Arize Phoenix
Written & Verified by Sampath Anji
Sampath Anji is a technology researcher, systems developer, and digital creator based in Telangana, India. He specializes in on-device AI architectures, autonomous agent workflows, high-throughput inference engines, and digital media production. Every tutorial on ISMARTANJI CREATIONS is grounded in code reproducibility, verified documentation, and transparent test environments. Read our full testing methodology on our About Us page, or submit feedback and code updates via our Contact Desk.