Build a Hybrid Search Engine with pgvector & FastAPI
Step-by-step engineering tutorial to building a production hybrid search engine combining full-text search, pgvector HNSW, RRF, and FastAPI.
Tech Guides & AI Innovations
Step-by-step engineering tutorial to building a production hybrid search engine combining full-text search, pgvector HNSW, RRF, and FastAPI.
Learn how to build low-latency on-device AI apps for Android in 2026 using Android AICore, Gemini Nano, ExecuTorch, and Jetpack Compose.
Learn how to build responsive real-time voice AI agents using WebRTC, LiveKit, Silero VAD, streaming LLMs, and chunk-based neural speech synthesis in Python, targeting a sub-500ms conversational roundtrip (with our empirical testbed benchmark averaging 480ms on fiber broadband). How to Build Real-Time Voice AI Agents with WebRTC in 2026 Sources & Official Documentation LiveKit WebRTC … Read more
Compare SGLang vs vLLM in 2026. Analyze RadixAttention vs PagedAttention, multi-agent KV cache reuse, structured JSON decoding, and production serving trade-offs. SGLang vs vLLM in 2026: The High-Throughput Inference Showdown Sources & Official Documentation SGLang Research Paper & Repository: github.com/sgl-project/sglang — “Efficiently Programming and Serving Large Language Models with SGLang” (LMSYS Org / UC Berkeley). … Read more
Learn how to build resilient autonomous browser agents using Playwright, vision-language models, accessibility tree pruning, and self-healing action loops. How to Build Autonomous Browser Agents with Playwright in 2026 Automating interactions across modern web applications has reached a critical breaking point. For over a decade, software engineering teams depended on deterministic browser automation frameworks like … Read more
Compare vLLM vs Ollama in 2026. Discover throughput benchmarks, memory management, latency comparisons, API integration, and production deployment tips vLLM vs Ollama in 2026: Architecture, Memory Footprint, and Deployment Guide Running language models on local hardware was once an experimental hobby reserved for researchers with high-end workstations. Today, local inference forms the backbone of private … Read more
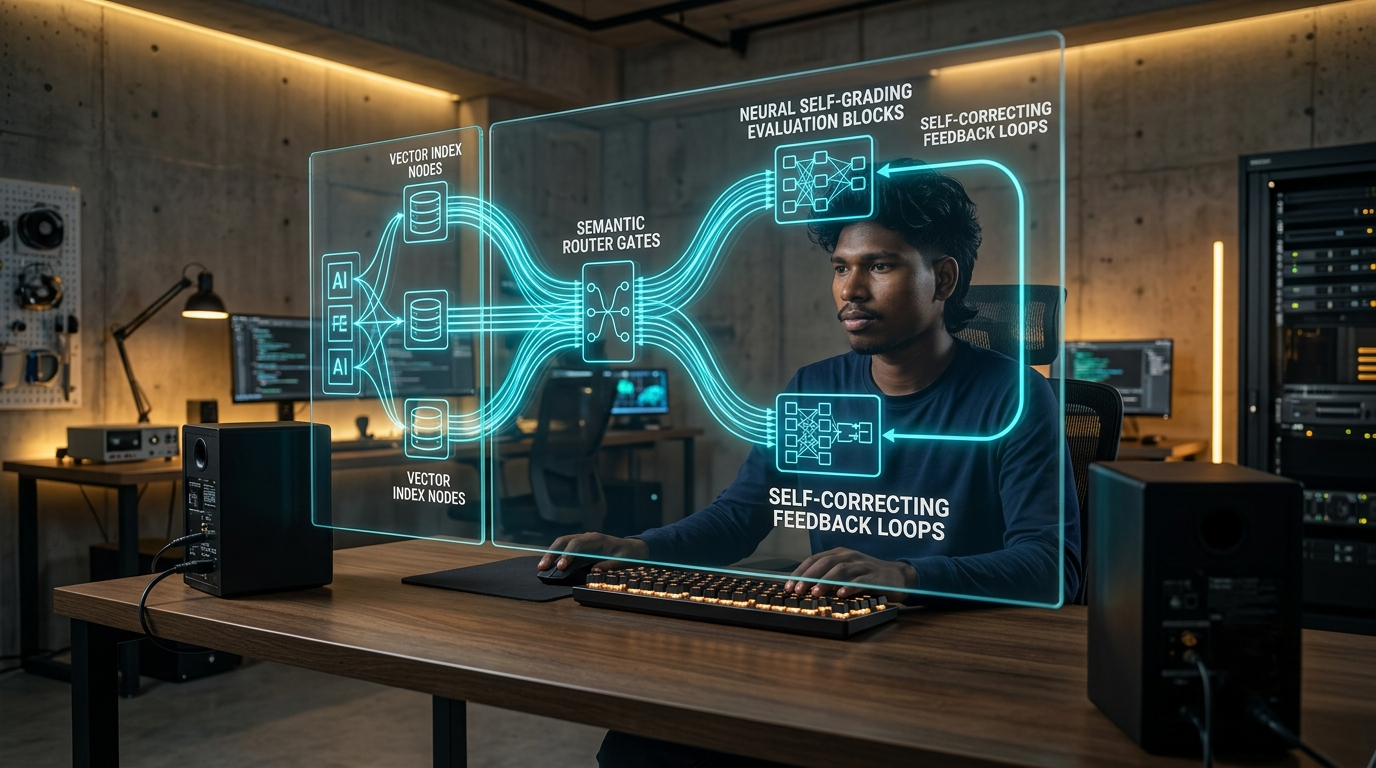
Master Agentic RAG architecture in 2026. Learn query routing, corrective retrieval loops, self-grading pipelines, and production implementation code. Agentic RAG Architecture in 2026: The Ultimate Developer Guide Dumping thousands of unstructured documents into a vector database and running top-k cosine similarity search was once considered the gold standard for enterprise artificial intelligence. In early prototypes, … Read more
LangGraph vs CrewAI in 2026 comparison. In-depth architectural review of state machines vs role-based multi-agent orchestration, latency benchmarks, and code. LangGraph vs CrewAI: Multi-Agent Orchestration & State Machine Comparison Single-prompt language model calls no longer satisfy the demands of modern enterprise automation. As software teams build autonomous systems capable of executing multi-step research, refactoring codebases, … Read more
Discover Embodied AI and Robotics Frameworks: Simulation, VLA Models, and Control Pipelines. Master embodied AI, GPU simulation, imitation learning, and vision-action models. Embodied AI and Robotics Frameworks: Simulation, VLA Models, and Control Pipelines Programming physical robots used to require writing rigid kinematic equations, hardcoding motion trajectories, and tuning PID controllers for months. When lighting conditions … Read more
Discover Vector Database Architecture for AI: Indexing, Latency, and Enterprise Scale. Master high-speed similarity search, hybrid retrieval, RAG caching, and vector indexing. Vector Database Architecture for AI: Indexing, Latency, and Enterprise Scale Context windows keep expanding, but dumping millions of raw tokens into language model prompts wrecks your API budget and introduces severe latency. Storing … Read more