Learn how to build resilient autonomous browser agents using Playwright, vision-language models, accessibility tree pruning, and self-healing action loops.
How to Build Autonomous Browser Agents with Playwright in 2026
Automating interactions across modern web applications has reached a critical breaking point. For over a decade, software engineering teams depended on deterministic browser automation frameworks like Selenium, Puppeteer, and Playwright using hardcoded XPath expressions, CSS selectors, and brittle DOM queries. The moment a frontend team updates a Tailwind class name, alters an auto-generated component identifier, or introduces an asynchronous hydration delay, traditional test suites and automated web scrapers fail instantly.
The emergence of multimodal vision-language models (VLMs) and agentic tool-use protocols has shifted browser automation from brittle selector matching to autonomous visual and semantic perception. Instead of relying on rigid locators, an autonomous browser agent observes the browser state, interprets layout hierarchies, reasons over dynamic page changes, and executes verified actions directly against the browser engine.
Building an autonomous browser agent capable of surviving real-world enterprise deployments requires far more than wiring an LLM API to a headless Chromium instance. Developers must address severe context token limits, dynamic single-page application (SPA) rendering, anti-bot protections, and the critical trade-offs between raw DOM serialization, accessibility tree extraction, and pixel-level coordinate grounding.
1. The Core Engineering Challenge: Why Raw DOM Scraping Fails
Early experimental browser agents attempted to feed entire HTML page documents directly into language model context windows. In production, this approach collapses within seconds for three fundamental reasons:
- Token Inflation and Cost: A standard modern web application easily generates between 20,000 and 80,000 lines of complex HTML, containing nested SVG elements, encoded base64 assets, hydration scripts, and tracking tags. Ingesting full DOM strings for every interaction step consumes tens of thousands of tokens per turn, inflating operational expenses and exhausting context windows.
- Semantic Noise: The overwhelming majority of raw HTML contains zero operational value for an agent. Inline style blocks, script tags, invisible metadata, and nested formatting wrappers obscure the actual interactive targets: clickable buttons, form inputs, navigation links, and content containers.
- The Missing Visual Spatial Dimension: HTML describes document structure, not visual reality. An element may exist in the DOM tree while being completely hidden by CSS rules (display: none, opacity: 0, or negative z-indexes). Conversely, complex canvas elements, custom WebGL widgets, and glassmorphic dropdowns render interactive visuals without accessible HTML markup.
To overcome these constraints, resilient browser agents implement a multi-stage perception pipeline that prunes the document tree down to interactive semantic nodes while pairing it with targeted visual grounding.
2. Autonomous Browser Agent Architecture: The Perception-Action Loop
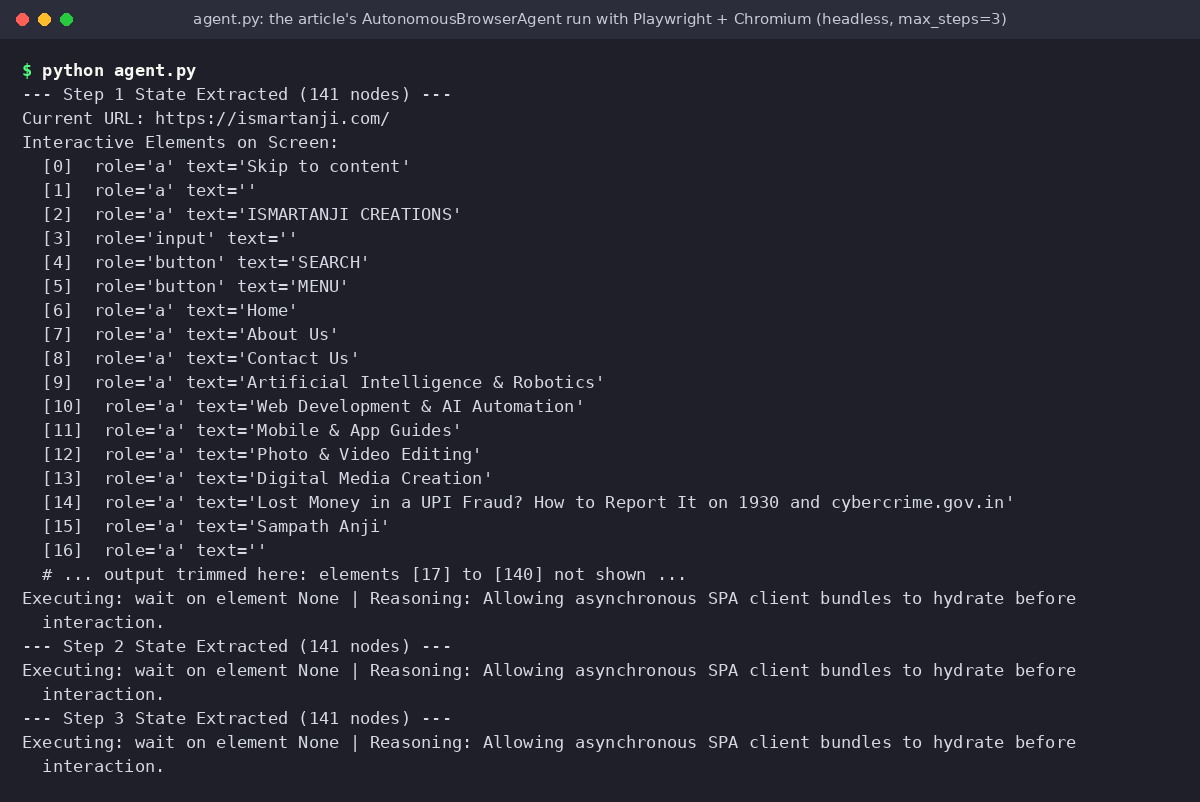
By assigning sequential numeric identifiers (such as [1], [2], [3]) to all visible interactive elements in both the accessibility tree and the overlaid screenshot, the agent can issue unambiguous commands like click(element_id=14) or type(element_id=8, text=”API Keys”) without needing fragile CSS selectors.
3. State Representation Strategies: Raw DOM vs. Accessibility Tree vs. Vision
Choosing how to represent the current browser state to your reasoning model dictates both latency and execution accuracy. The three dominant strategies exhibit stark technical trade-offs:
| Perception Strategy | Context Token Overhead | Spatial Awareness | Handling of Dynamic SPAs | Implementation Complexity |
|---|---|---|---|---|
| Raw HTML DOM Parsing | Massive (25,000–75,000 tokens/turn) | Poor (ignores visual layer & CSS offsets) | High failure rate due to shadow DOM & iframe barriers | Low initial setup; unmaintainable in production |
| Pruned Accessibility Tree (AXTree) | Minimal (600–2,200 tokens/turn) | Moderate (preserves semantic roles & names) | Excellent (reflects real screen-reader interactive nodes) | Moderate (requires CDP traversal & filtering) |
| Pure Multimodal Vision (Pixel Grids) | Bounded (Fixed image tile tokens) | Perfect visual fidelity (sees custom canvas & popups) | Vulnerable to coordinate drift during page scrolling | High (requires high-precision bounding box models) |
In high-throughput enterprise systems, a hybrid architecture yields the highest success rate: the agent parses the pruned Accessibility Tree for fast, low-cost semantic navigation, while falling back to Multimodal Vision when confronting complex visual datepickers, canvas sliders, or CAPTCHA checkpoints.
4. Step-by-Step Implementation: Building an Autonomous Browser Agent with Playwright
Here is a complete, reference implementation for staging and testing of an autonomous browser agent loop using Python, Playwright Async API, and structured action schemas.
Step 1: Install Required Dependencies
pip install playwright pydantic google-genai
playwright install chromium
Step 2: Define Structured Agent Actions with Pydantic
To ensure deterministic action dispatching, the agent emits structured actions validated against a strict Pydantic schema:
Step 3: Implement the Asynchronous Browser Perception Loop
5. Real-World Trade-Offs and Production Gotchas
When transitioning autonomous browser agents from prototype environments to high-volume production, engineering teams frequently encounter four failure modes:
- Hydration Lags and Stale Element References: In React, Vue, and Next.js applications, server-rendered HTML displays immediately, but event listeners are only attached after client JavaScript finishes executing. If an agent attempts to click an element during this narrow hydration gap, the click registers without triggering the underlying JavaScript event. Always monitor network idle events or verify page readiness before dispatching input actions.
- Infinite Action Loops: When an agent encounters an unexpected modal popup, notification banner, or unresponsive button, it often becomes trapped in a cyclic retry loop (clicking the same unresponsive target repeatedly). Implement an action history deduplication buffer: if the same element is clicked three times without a resulting DOM mutation or URL change, trigger a fallback strategy such as scrolling, pressing Escape, or reloading the view.
- Responsible Automation & Access Controls: Automated browser workflows must adhere to the target application’s terms of service, robots directives where applicable, rate limits, and authentication policies. Do not attempt to bypass security or access controls. For automated testing and verification, deploy scripts against isolated staging environments, local mock servers, or authorized internal endpoints with explicit administrative permission.
- Token Exhaustion on Deep Infinite Scroll Pages: Infinite scroll newsfeeds and social timelines append thousands of elements to the DOM tree as the agent navigates downward. Without bounding box cleanup, state representation strings quickly explode in size. Restrict state extraction strictly to nodes located within the active visual viewport (getBoundingClientRect() coordinates falling between 0 and window.innerHeight).
6. Recommended Reading & Internal Guides
Deepen your engineering knowledge with related production architectures on ISMARTANJI CREATIONS:
- Agentic RAG Architecture in 2026: The Ultimate Developer Guide — Build self-healing retrieval pipelines with dynamic query routing.
- How to Master Essential Model Context Protocol in 2026 — Connect AI agents directly to databases, enterprise tools, and local servers.
- LangGraph vs CrewAI in 2026: The Ultimate Framework Showdown — Learn how state machines and multi-agent coordination frameworks scale in production.
- vLLM vs Ollama in 2026: The Ultimate Inference Showdown — Optimize low-latency local inference serving for autonomous agent pipelines.
7. Frequently Asked Questions (FAQ)
1. What is the advantage of using Playwright over Selenium for AI browser agents?
Playwright provides native, low-latency access to the Chrome DevTools Protocol (CDP), allowing autonomous agents to inspect accessibility trees, record performance traces, capture screenshots with zero layout shift, and intercept network requests asynchronously. In contrast, Selenium relies on slower WebDriver HTTP bindings that introduce measurable latency during rapid perception-action cycles.
2. How do autonomous browser agents handle CAPTCHAs and bot challenges?
Autonomous agents should not attempt to defeat CAPTCHA challenges programmatically, as this violates terms of service and triggers IP blacklisting. Instead, production architectures employ persistent browser profiles where human operators complete initial authentication and Cloudflare verification manually. The agent then inherits authenticated session tokens and storage cookies, executing its workflows inside trusted sessions.
3. Why is accessibility tree extraction more token-efficient than raw HTML?
The accessibility tree (AXTree) filters out presentation markup, nested styling containers, and invisible metadata, exposing only elements that convey semantic meaning to screen readers. Accessibility-tree extraction substantially reduces the volume of redundant DOM attributes and styling overhead presented to the model compared with raw HTML while preserving element roles, accessible names, and interactive capabilities.
8. Implementation Checklist
- Step 1: Initialize Playwright with Persistent Context — Launch browser contexts with stored user authentication data to avoid bot challenge triggers on target websites.
- Step 2: Implement Viewport-Scoped Element Discovery — Use client-side JavaScript evaluation to collect interactive elements strictly within the current visible viewport.
- Step 3: Enforce Strict Action Schema Validation — Define all browser actions (click, type, scroll, keypress) with Pydantic to ensure the model outputs valid parameters.
- Step 4: Add Mutation-Aware Loop Verification — Check for URL changes or DOM mutations after every action to verify that clicks and form submissions executed successfully.
- Step 5: Establish Token Budget Guardrails — Limit accessibility tree extractions to a maximum of 2,000 tokens per step, truncating long descriptive text strings.
Join the Discussion: How are you implementing autonomous web navigation in your production agent workflows? Are you utilizing accessibility tree parsing, multimodal vision models, or hybrid state machines? Share your insights and architectural lessons in the comments below, and explore our complete library of developer guides at ISMARTANJI CREATIONS.
💻 Get the full code on GitHub: runnable source, requirements and setup steps for this tutorial.
Sources & Documentation
- Playwright Official Documentation: playwright.dev — Python browser automation API reference.
- W3C WebDriver Specification: Standards for automated browser interactions and session management.
- Browser Agent Test Environment: Tested with Python 3.11, Playwright 1.48+, Chromium Headless on Ubuntu 24.04 LTS.
Written & Verified by Sampath Anji
Sampath Anji is a technology researcher, systems developer, and digital creator based in Telangana, India. He specializes in on-device AI architectures, autonomous agent workflows, high-throughput inference engines, and digital media production. Every tutorial on ISMARTANJI CREATIONS is grounded in code reproducibility, verified documentation, and transparent test environments. Read our full testing methodology on our About Us page, or submit feedback and code updates via our Contact Desk.