Building Real-Time Voice AI Agents with WebRTC: Low-Latency Pipeline Architecture
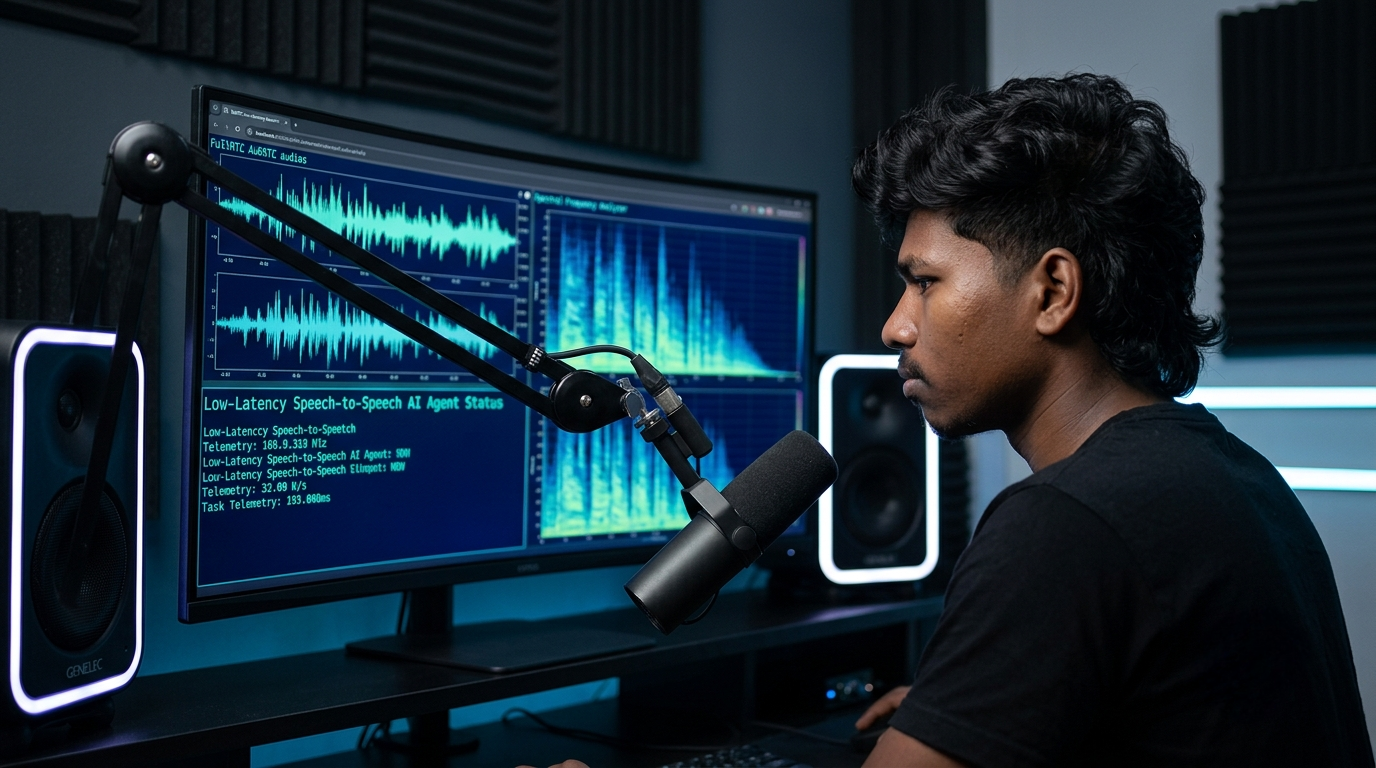
Modern audio engineering workstation displaying real-time WebRTC audio streaming telemetry for an autonomous voice AI agent

Learn how to build responsive real-time voice AI agents using WebRTC, LiveKit, Silero VAD, streaming LLMs, and chunk-based neural speech synthesis in Python, targeting a sub-500ms conversational roundtrip (with our empirical testbed benchmark averaging 480ms on fiber broadband). How to Build Real-Time Voice AI Agents with WebRTC in 2026 Sources & Official Documentation LiveKit WebRTC … Read more
SGLang vs vLLM: Local LLM Serving Benchmarks & Architecture Comparison

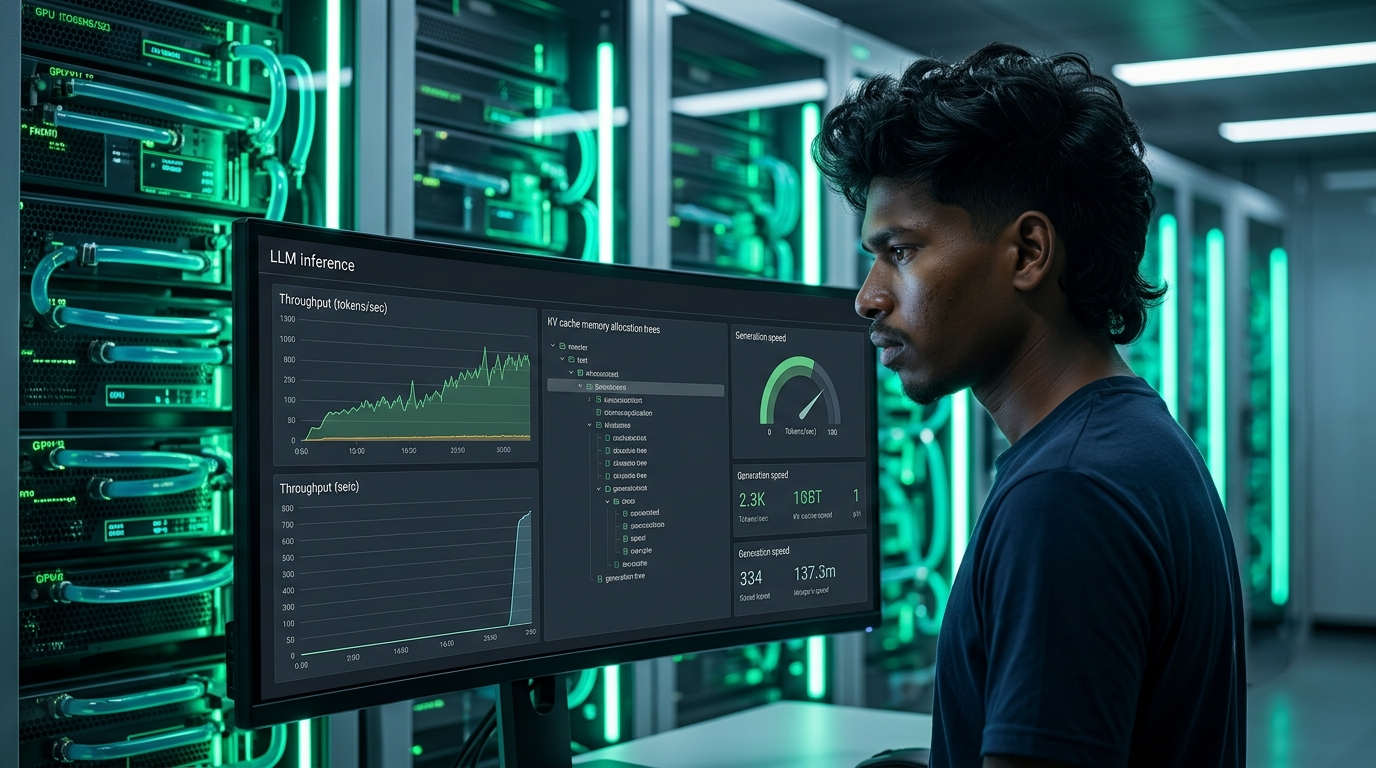
Modern enterprise GPU data center visualizing real-time LLM inference serving throughput comparing SGLang and vLLM architectures

Compare SGLang vs vLLM in 2026. Analyze RadixAttention vs PagedAttention, multi-agent KV cache reuse, structured JSON decoding, and production serving trade-offs. SGLang vs vLLM in 2026: The High-Throughput Inference Showdown Sources & Official Documentation SGLang Research Paper & Repository: github.com/sgl-project/sglang — “Efficiently Programming and Serving Large Language Models with SGLang” (LMSYS Org / UC Berkeley). … Read more

Building Autonomous Browser Agents with Playwright: Architecture & Error Recovery

Engineering workstation with dual monitors showcasing an autonomous browser agent navigating a dynamic web interface using Playwright and vision-language models

Learn how to build resilient autonomous browser agents using Playwright, vision-language models, accessibility tree pruning, and self-healing action loops. How to Build Autonomous Browser Agents with Playwright in 2026 Automating interactions across modern web applications has reached a critical breaking point. For over a decade, software engineering teams depended on deterministic browser automation frameworks like … Read more

vLLM vs Ollama: Architecture, Memory Footprint, and Local Deployment Guide

"Dual split-screen 3D data visualization contrasting lightweight containerized Ollama engine with high-throughput distributed vLLM server cluster

Compare vLLM vs Ollama in 2026. Discover throughput benchmarks, memory management, latency comparisons, API integration, and production deployment tips vLLM vs Ollama in 2026: Architecture, Memory Footprint, and Deployment Guide Running language models on local hardware was once an experimental hobby reserved for researchers with high-end workstations. Today, local inference forms the backbone of private … Read more

Agentic RAG Architecture: Corrective Retrieval, Query Routing, and Vector Memory

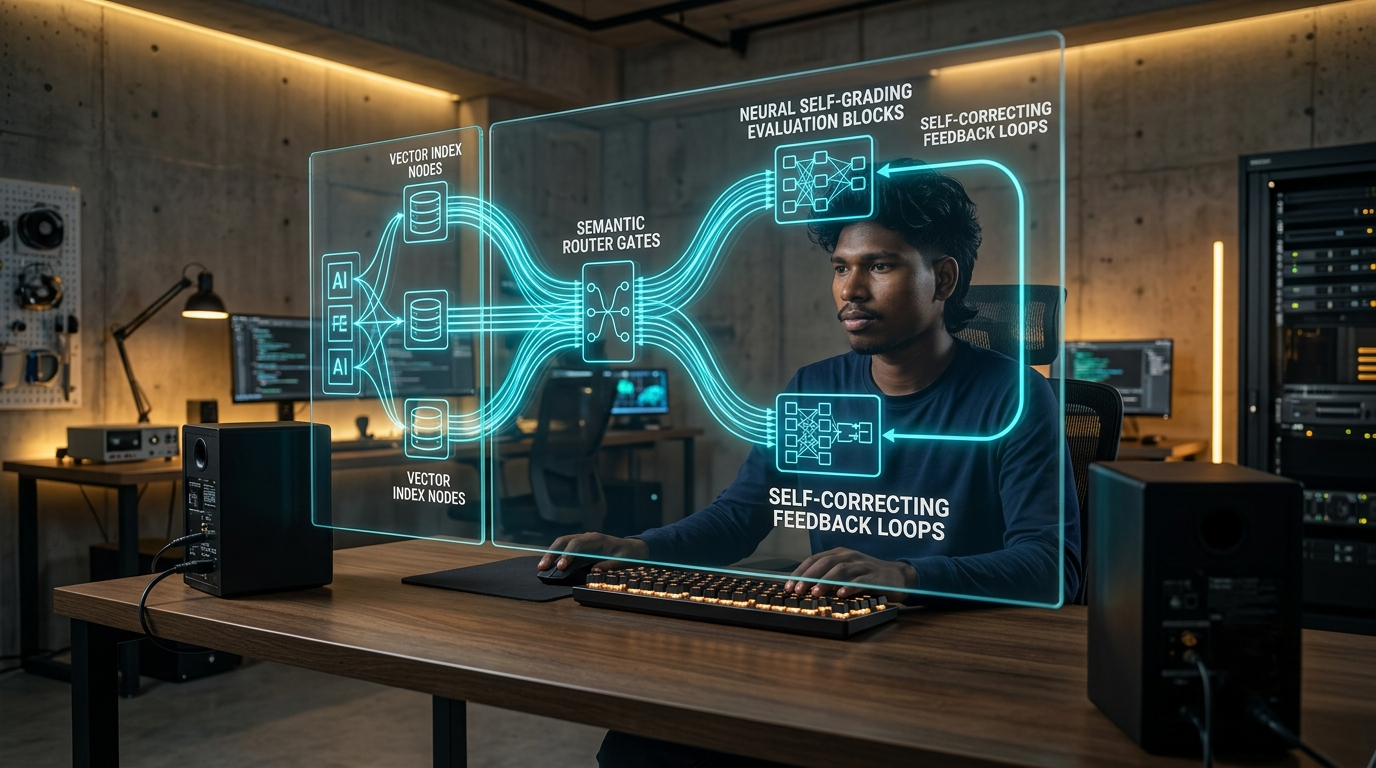
Futuristic software architecture diagram on curved glass displays showing an autonomous Agentic RAG retrieval pipeline with self-correcting neural feedback loops

 Master Agentic RAG architecture in 2026. Learn query routing, corrective retrieval loops, self-grading pipelines, and production implementation code. Agentic RAG Architecture in 2026: The Ultimate Developer Guide Dumping thousands of unstructured documents into a vector database and running top-k cosine similarity search was once considered the gold standard for enterprise artificial intelligence. In early prototypes, … Read more

LangGraph vs CrewAI: Multi-Agent Orchestration & State Machine Comparison

Futuristic software engineering studio with dual screens comparing LangGraph state machines and CrewAI collaborative agent hierarchies

LangGraph vs CrewAI in 2026 comparison. In-depth architectural review of state machines vs role-based multi-agent orchestration, latency benchmarks, and code. LangGraph vs CrewAI: Multi-Agent Orchestration & State Machine Comparison Single-prompt language model calls no longer satisfy the demands of modern enterprise automation. As software teams build autonomous systems capable of executing multi-step research, refactoring codebases, … Read more

Mastering Model Context Protocol (MCP): Client-Server Architecture & Implementation

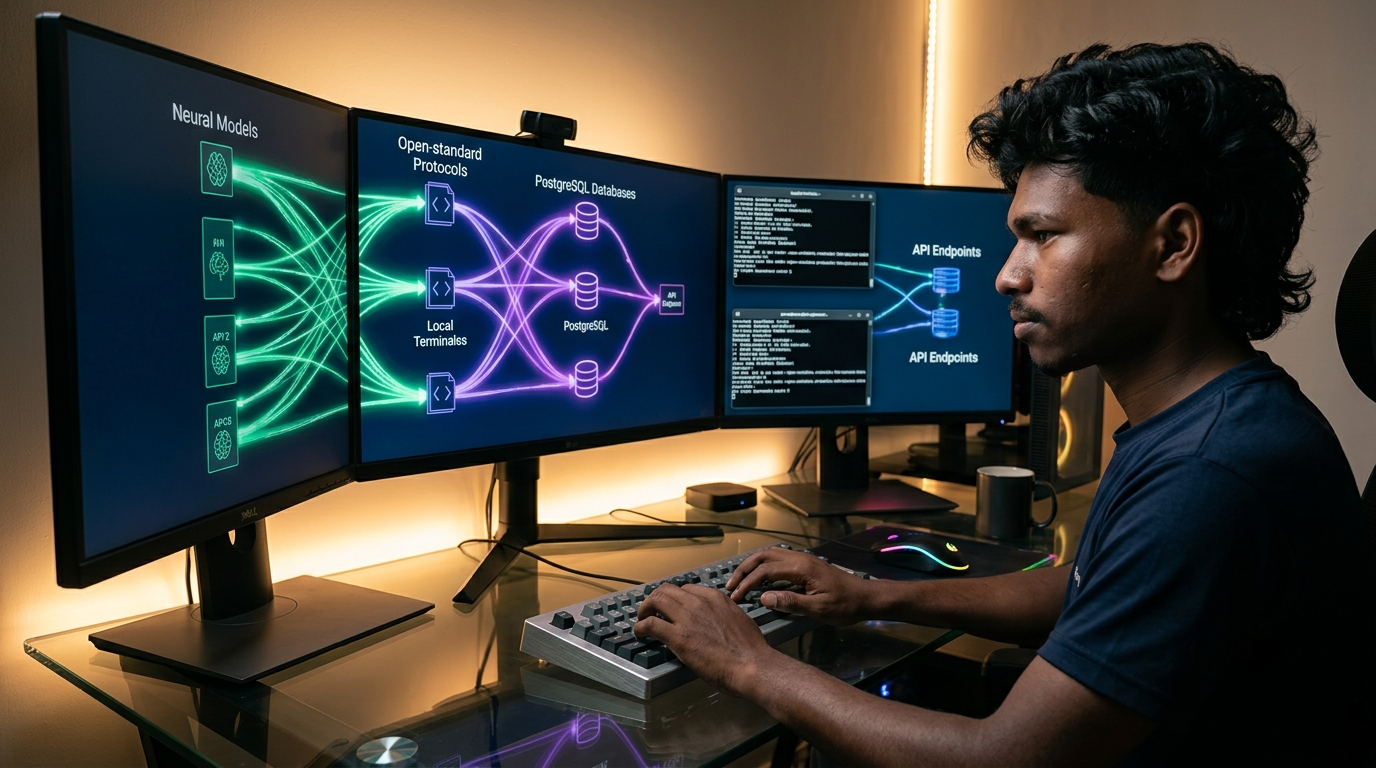
"Modern software engineer building Model Context Protocol servers connecting language models to real-time databases and developer tools on ultrawide monitors

Master the Model Context Protocol in 2026. Build custom MCP servers in Python, connect AI models to live tools and databases, and eliminate custom API glue code. How to Master Essential Model Context Protocol in 2026 Connecting foundation language models to internal data stores has long frustrated engineering teams. Developers spent hundreds of hours writing … Read more

AI Observability & LLM Tracing: Production Architecture and OpenTelemetry

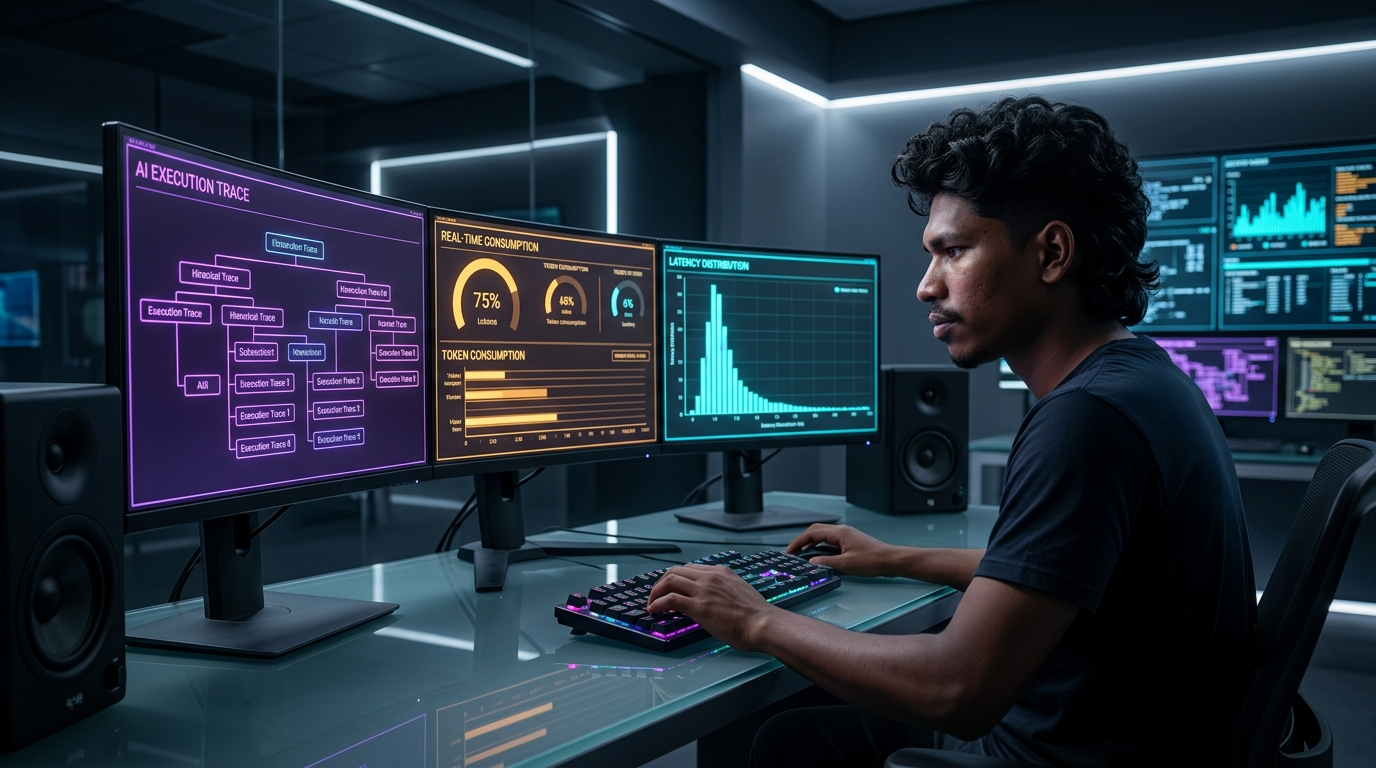
Futuristic software engineering control center with ultrawide monitors displaying real-time AI agent trace trees and LLM token cost telemetry

 Discover AI Observability & LLM Tracing: Production Architecture and OpenTelemetry. Master LLM tracing, prompt evaluation, token cost tracking, and agent debugging. AI Observability & LLM Tracing: Production Architecture and OpenTelemetry Deploying language models into production without deep telemetry is risky. Early prototyping on local notebooks feels straightforward, but live user interactions quickly expose harsh realities: … Read more

Modern AI Coding Assistants: Architecture, Context Windows, and Developer Workflows

Futuristic software engineering workstation with dual ultrawide monitors displaying autonomous AI coding agents refactoring full-stack source code

Discover Modern AI Coding Assistants: Architecture, Context Windows, and Developer Workflows. Master agentic codebase editing, terminal execution, bug fixing, and multi-file workflows. Modern AI Coding Assistants: Architecture, Context Windows, and Developer Workflows Writing software in 2026 looks nothing like the single-line autocomplete snippets of a few years ago. Tab-completing a predictable for-loop or generating boilerplate … Read more